Apr. 2026
– Present2026.04
— 至今
– Present2026.04
— 至今
THUNLP & Qiyuan Lab启元实验室
Research on Earth observation agents, focusing on long-horizon, real-world tasks.开展地球观测 agent 研究,聚焦长程真实任务的处理。
Ph.D. Student in Hydrological Modeling UCAS水文建模方向博士研究生 中国科学院大学
Last updated: October 9, 2026更新日期:2026 年 10 月 9 日
I am a Ph.D. student at the University of Chinese Academy of Sciences (UCAS) and the Institute of Geographic Sciences and Natural Resources Research, Chinese Academy of Sciences. My research centers on hydrological modeling, including the development of differentiable physics-based hydrological models and high-resolution groundwater mapping.我目前就读于中国科学院大学与中国科学院地理科学与资源研究所,攻读博士学位。我的研究围绕水文建模展开,主要开展可微分物理水文模型开发与高分辨率地下水制图。
Since April 2026, I have collaborated with THUNLP & Qiyuan Lab on Earth observation agents.自 2026 年 4 月起,我与启元实验室合作开展地球观测 agent 研究。
I am seeking internship opportunities in AI agent research.我正在寻找AI agent 研究方向的实习机会,欢迎与我联系。
Contact me:联系方式:yuzhounan22@mails.ucas.ac.cn+86 135 6315 2549
Research on Earth observation agents, focusing on long-horizon, real-world tasks.开展地球观测 agent 研究,聚焦长程真实任务的处理。
Research on hydrological modeling.开展水文建模研究。
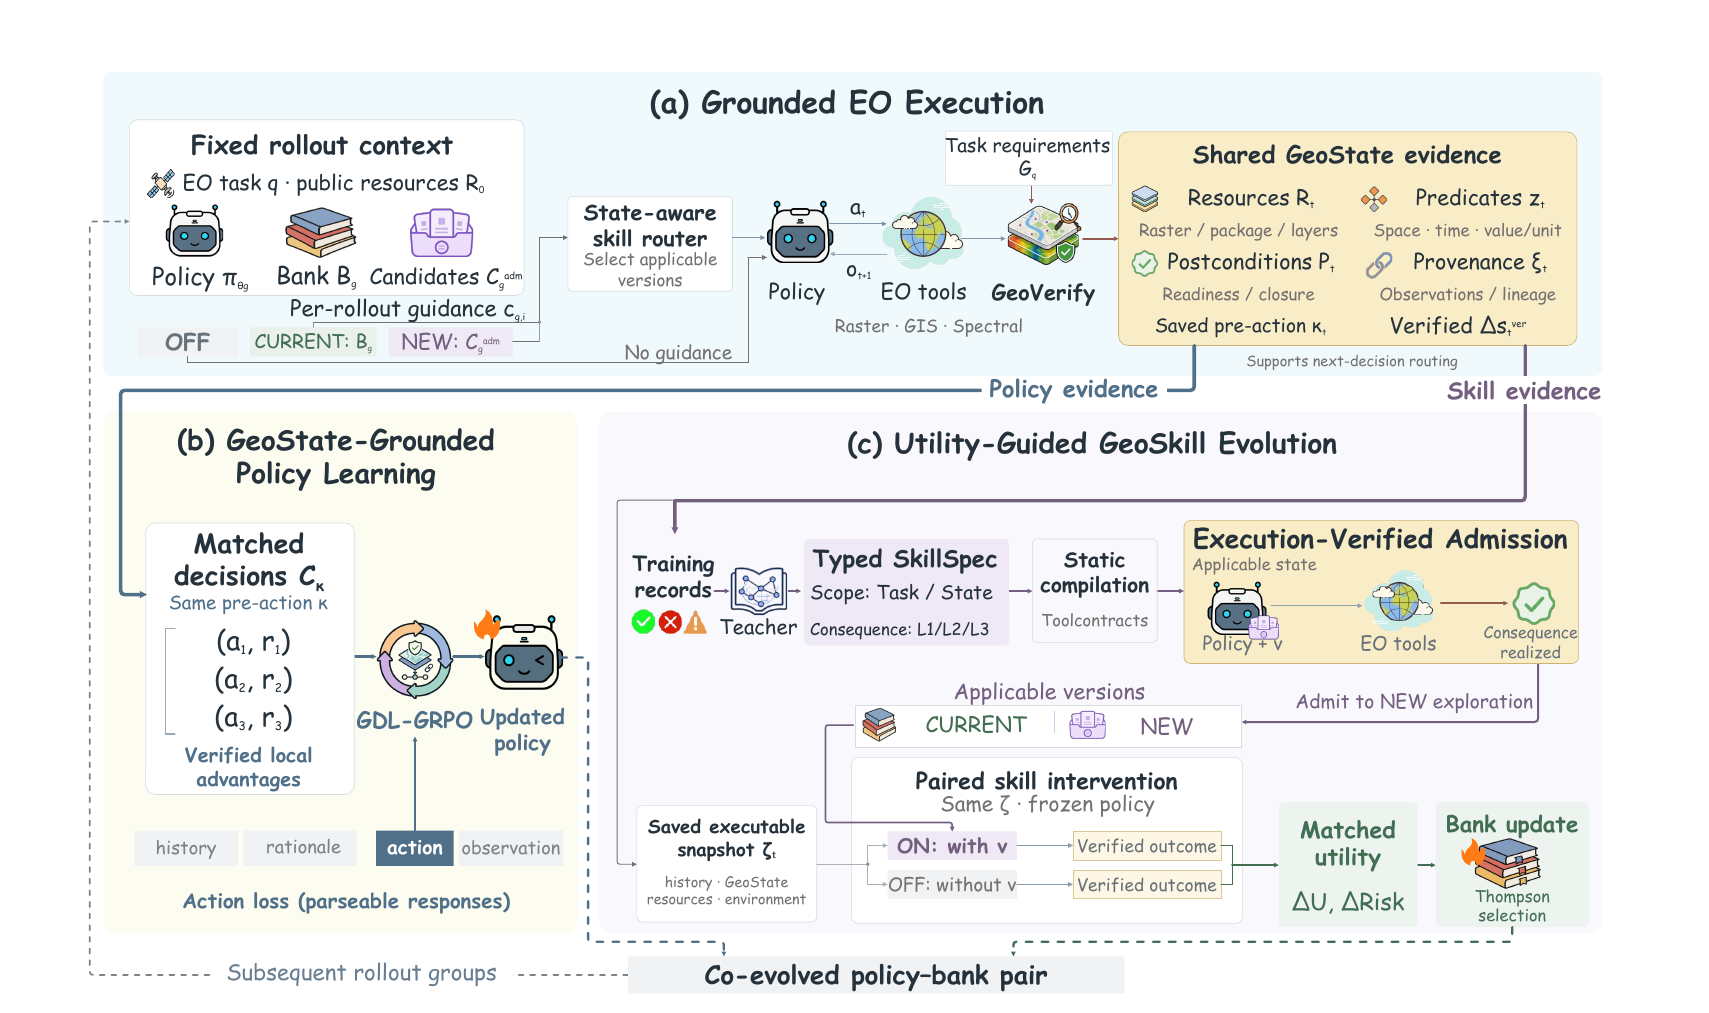
Built an Earth observation agent framework on Qwen3.5-9B that uses reinforcement learning to co-evolve the model’s policy and a reusable skill bank. Verified task progress guides policy updates, while execution-based tests select and refine skills that help the agent complete multi-step tasks. The improved skills support subsequent training, and the policy retains most of the co-evolution gains even when the skill bank is disabled.基于 Qwen3.5-9B 构建地球观测 agent 框架,通过 RL 推动模型的 policy 与可复用 skill bank 协同进化。以可验证的任务进展指导 policy 更新,并通过实际执行测试筛选和改进有助于完成多步任务的 skill,再用这些 skill 支持后续训练。训练后的 policy 即使关闭 skill bank,仍能保留大部分协同进化带来的提升。
On the 1,169-task OpenEarthAgent test set, the 9B agent outperforms GPT-5.5 on both answer score (50.37 vs. 47.97) and generation-tool execution score (77.01 vs. 66.90). Compared with training the same 9B model using Standard GRPO, our co-evolution training method improves answer score and generation-tool execution score by 7.87 and 12.18 percentage points, respectively, under matched policy-training rollout budgets.在包含 1,169 个任务的 OpenEarthAgent 测试集上,9B agent 的答案得分(50.37 vs. 47.97)和生成类工具执行得分(77.01 vs. 66.90)均超过 GPT-5.5。相比使用 Standard GRPO 训练同一个 9B 模型,在相同 policy 训练 rollout 预算下,我们的协同进化训练方法使答案得分和生成类工具执行得分分别提升 7.87 和 12.18 个百分点。
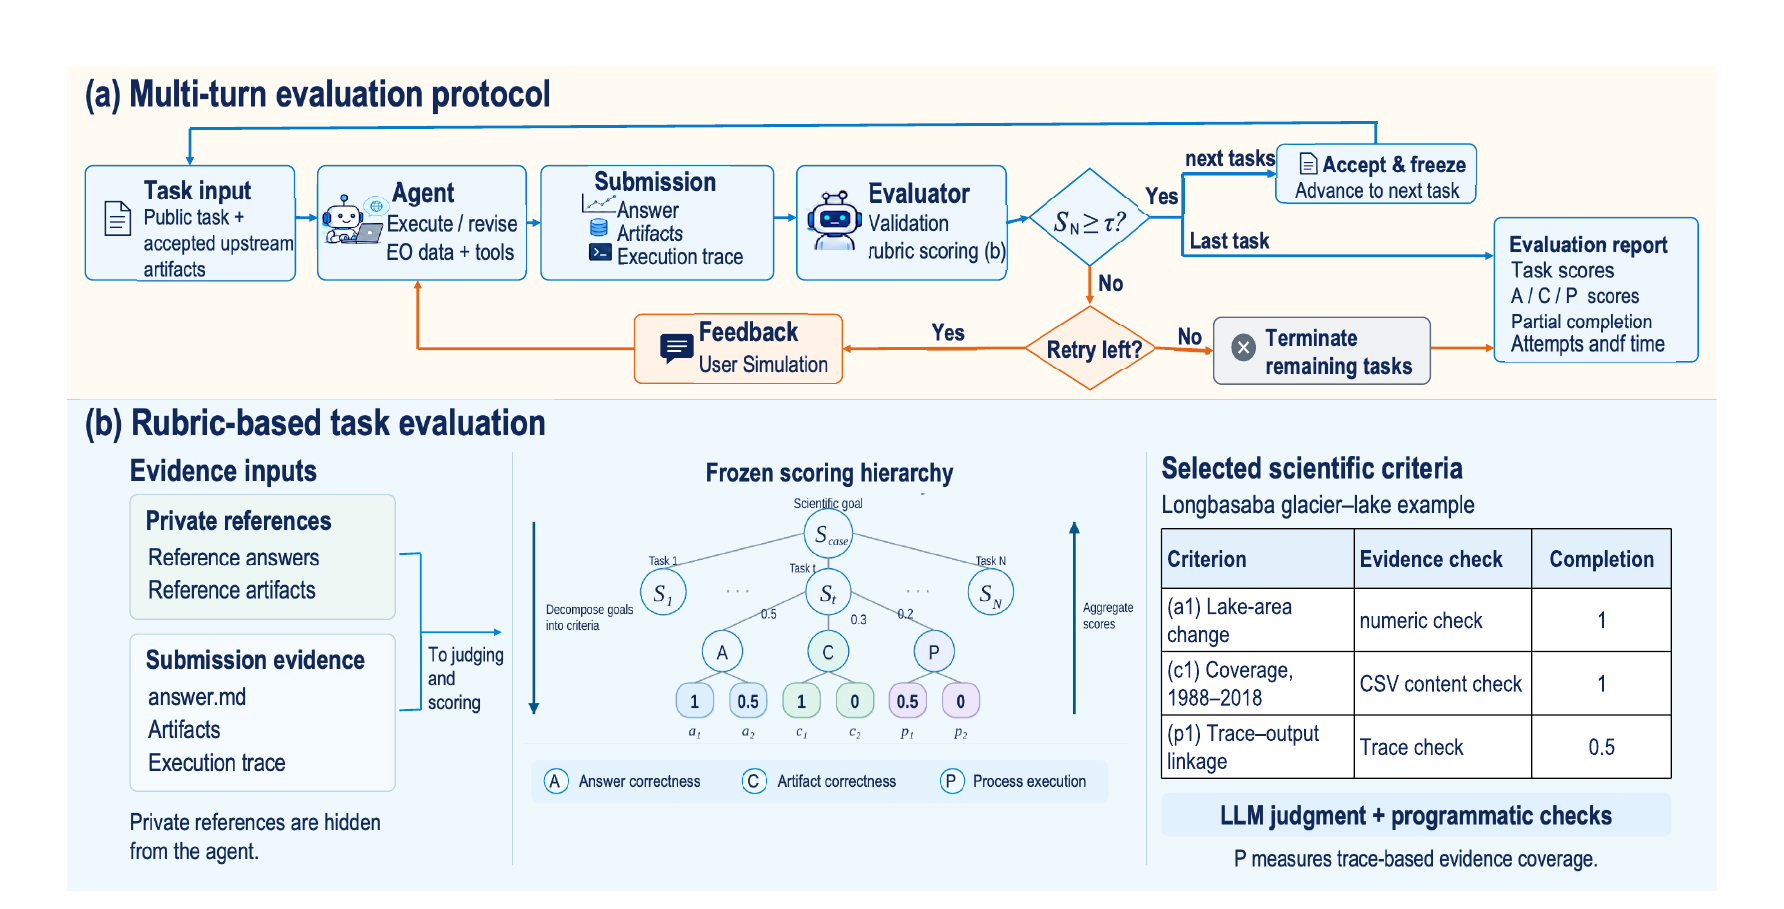
Built 101 subtasks from 30 peer-reviewed publications, covering real-world, long-horizon scientific investigations in Earth observation. Each case links subtasks through intermediate artifacts around a scientific objective, with reproduced reference results and human-reviewed scoring rubrics. Scientific conclusions are linked to supporting artifacts and execution evidence to assess agents’ ability to maintain scientific validity throughout the workflow. Evaluation spans six language models and three agent harnesses, with the best configuration achieving a case-averaged Rubric score of 44.3. These results highlight substantial room for improvement in current agents’ ability to reliably complete real-world, long-horizon scientific tasks.基于 30 篇同行评审论文构建 101 个子任务,覆盖真实、长程的地球观测科学研究。每个案例围绕一个科学目标,通过中间产物串联子任务,并提供复现的参考结果与经人工审核的 rubric,将科学结论与支撑产物、执行证据关联起来,评估 agent 在完整工作流中保持科学有效性的能力。评测覆盖 6 个语言模型与 3 种 agent harness,最佳配置的案例平均 rubric 得分为 44.3。结果表明,现有 agent 在可靠完成真实、长程科学任务方面仍有明显提升空间。
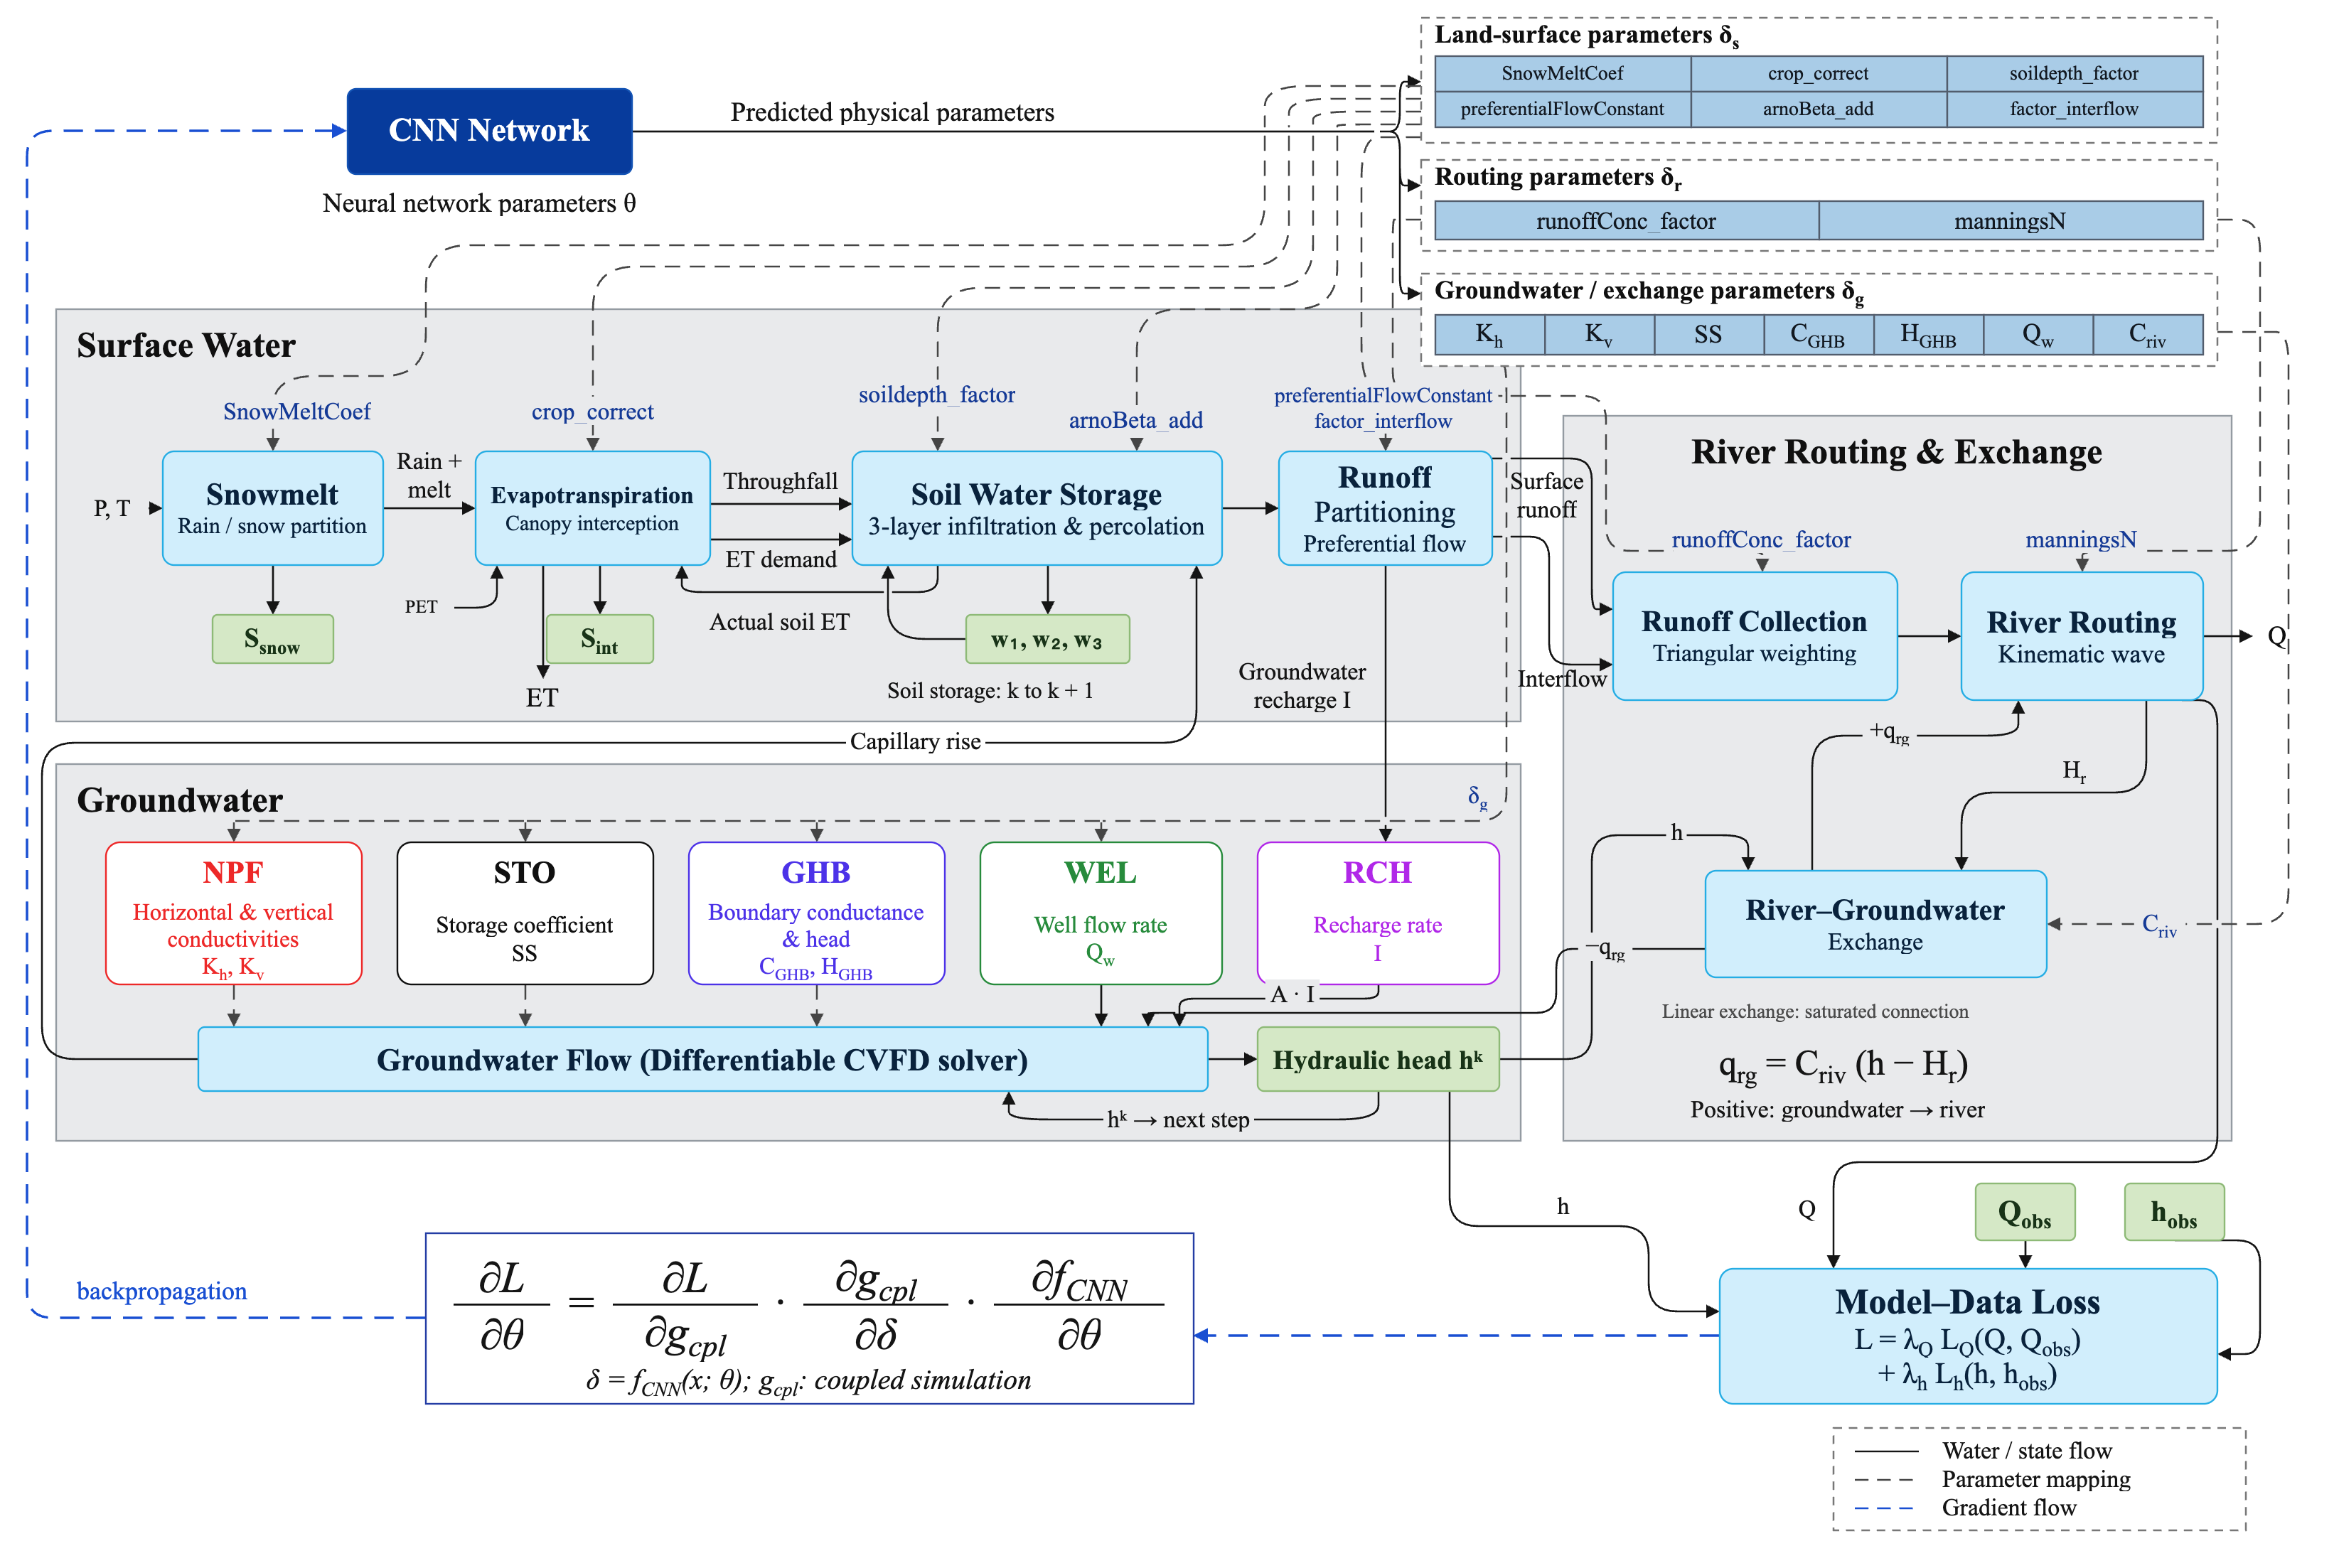
Developing differentiable hydrological models for detailed groundwater-depth simulation and recovery analysis in the North China Plain, and exploring groundwater mapping methods that combine physical simulation with machine learning. Using CWatM–MODFLOW simulation outputs together with precipitation, soil properties, and other data, a random forest learns the residuals between observations and simulations to produce high-resolution groundwater-level maps. Model refinement is guided by bad case analysis and physical consistency checks during debugging.面向华北平原地下水埋深精细模拟与恢复分析,开展可微分水文模型搭建,并探索物理模拟与机器学习相结合的地下水制图方法。以 CWatM–MODFLOW 物理模型的模拟结果为数据基础,结合降水、土壤属性等数据,利用随机森林学习观测与模拟之间的残差,绘制高分辨率地下水位地图。在模型调试过程中,通过 bad case 分析与物理一致性检验调整模型。
Zhounan Yu et al. (Second author)(第二作者)
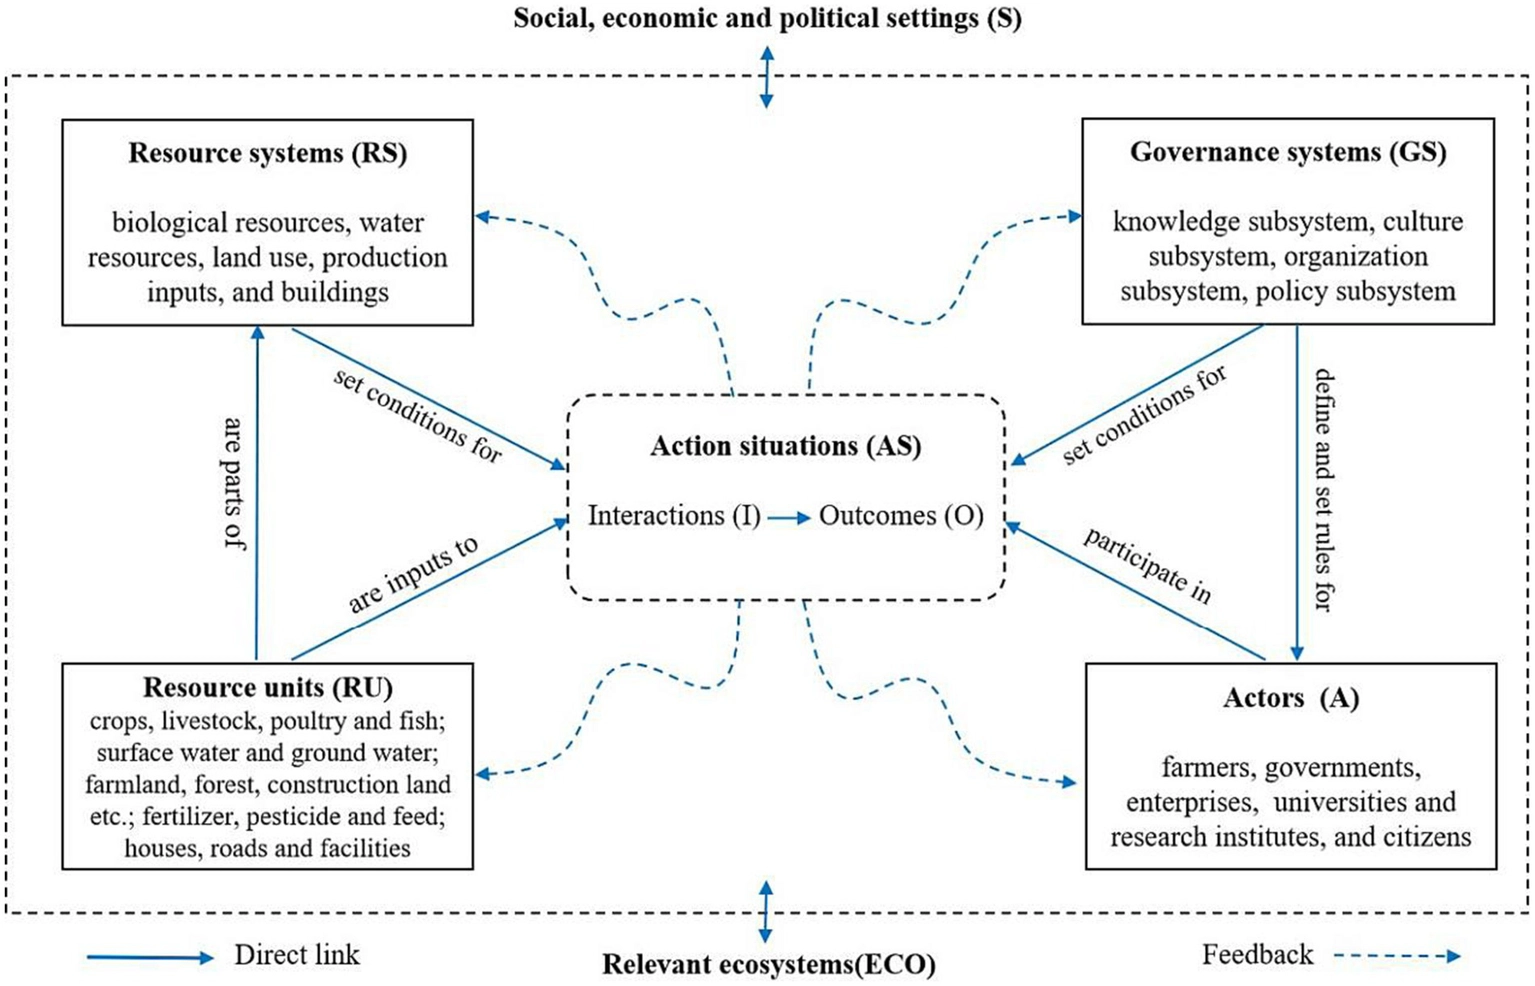
Developed an analytical framework for quantifying social–ecological resilience, using indicators such as ecosystem-service trade-offs and carbon footprint per unit economic output to analyze changes in system functioning and adaptive capacity as management practices change. This research built knowledge of ecosystem services, environmental disturbances, and adaptation mechanisms, providing a foundation for understanding system resilience and adaptation in the context of climate change.围绕社会—生态系统韧性的量化表征,构建分析框架,通过生态系统服务之间的权衡与单位产值碳足迹等指标,分析管理措施变化下系统功能与适应能力的变化。这项研究积累了生态系统服务、环境扰动与适应机制方面的知识,为理解气候变化背景下的系统韧性与适应问题提供基础。
Zhounan Yu et al. (First author)(第一作者)
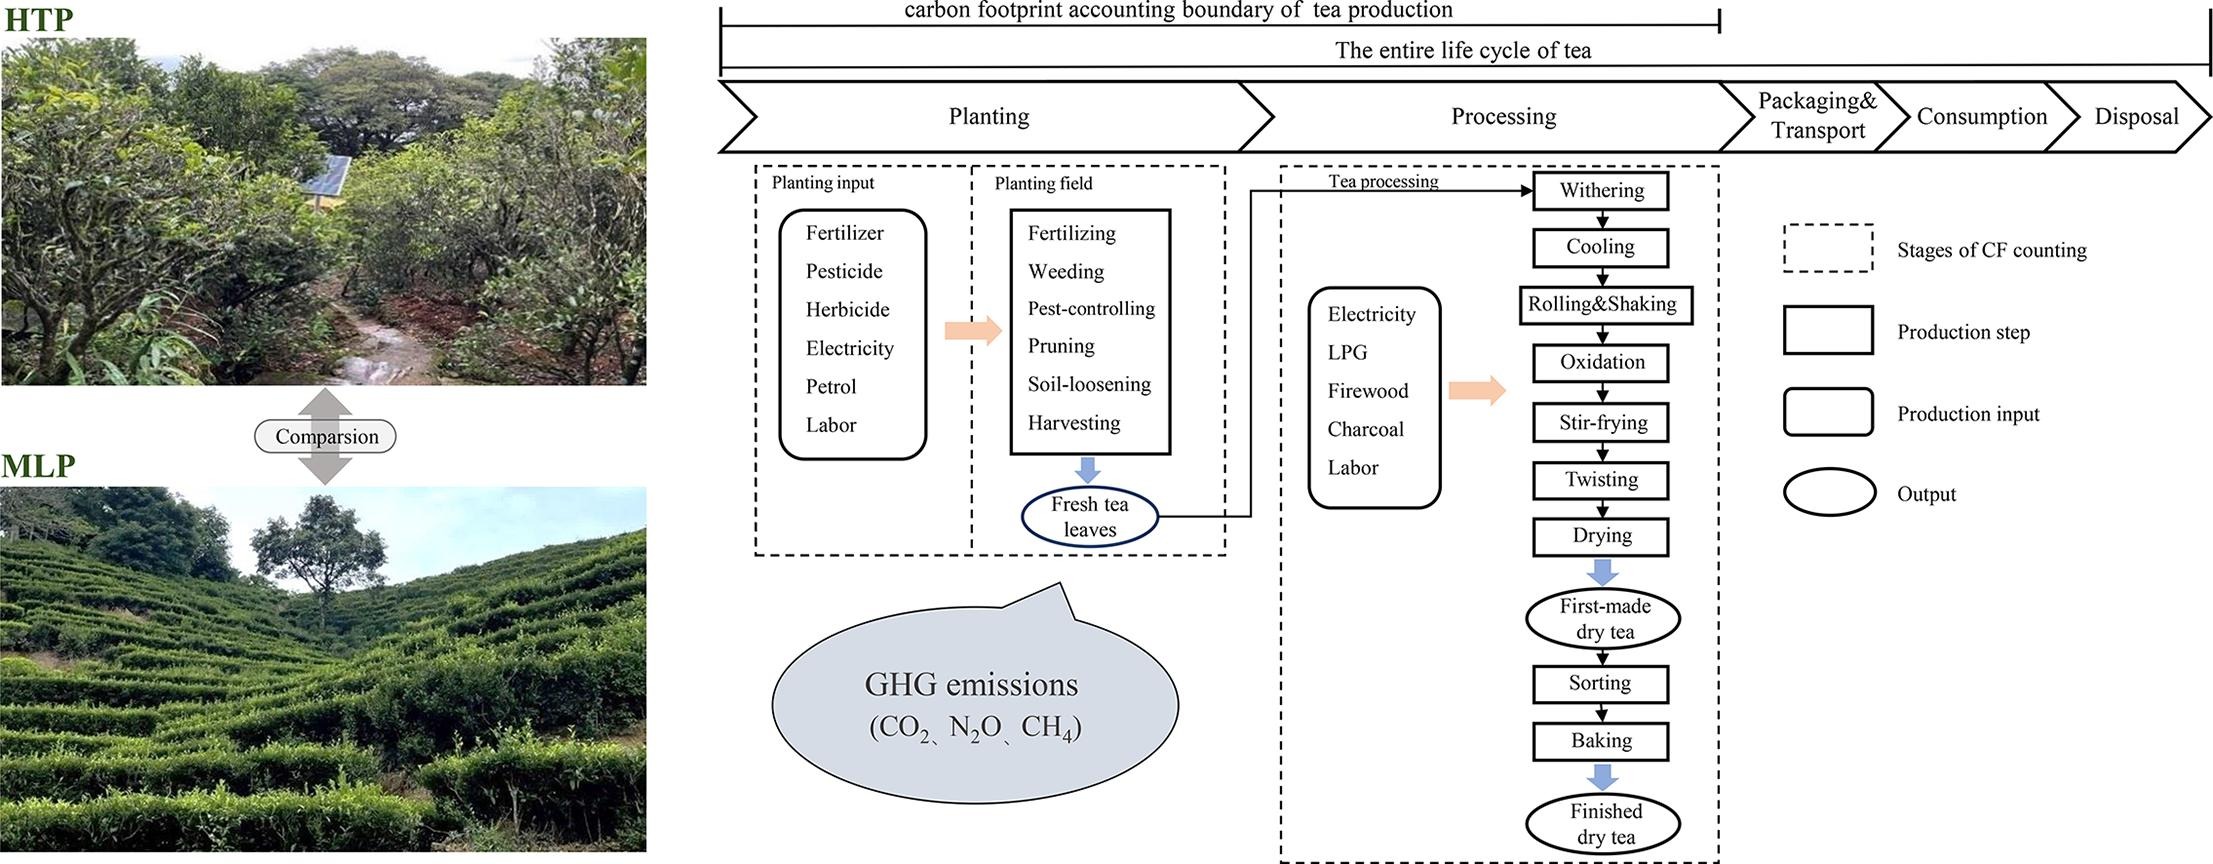
Conducted carbon footprint accounting for production systems, quantifying greenhouse gas emissions across cultivation and processing, and analyzed how fertilizer use, energy inputs, and management practices affect emissions. Comparing emission sources and mitigation pathways built an understanding of trade-offs among resource use, economic returns, and environmental impacts, providing a foundation for analyzing the relationship between low-carbon transitions and system resilience.开展生产系统碳足迹核算,量化种植与加工环节的温室气体排放,分析施肥、能源投入及管理措施对排放的影响。通过比较排放来源与减排途径,理解资源利用、经济收益和环境影响之间的权衡,为分析低碳转型与系统韧性的关系积累知识基础。
Integrated master’s–doctoral program
GPA: 3.87/4 · Director’s Scholarship; Institute Merit Student硕博连读
平均成绩:3.87/4 · 所长奖学金、所三好学生
Undergraduate
GPA: 93.53/100 · National Scholarship; Outstanding Graduate; Outstanding Undergraduate Thesis本科
平均成绩:93.53/100 · 国家奖学金、优秀毕业生、优秀毕业论文